Projects

Computer-Use GUI Agent: Post-Training and Self-Evolving Evaluation

Computer-Use GUI Agent: Post-Training and Self-Evolving Evaluation

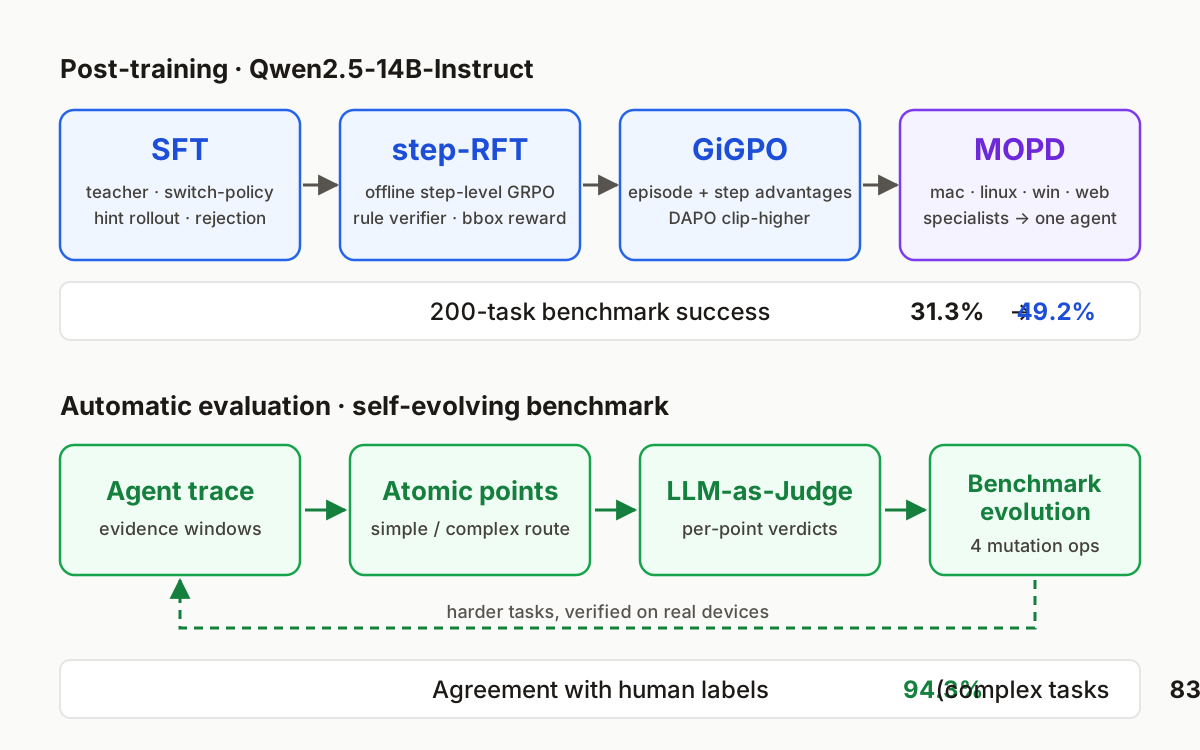
Post-training and evaluation for a computer-use agent that runs multi-step workflows on real web and desktop interfaces. On Qwen2.5-14B-Instruct, an SFT → offline step-RFT → online GiGPO pipeline lifts success on a 200-task expert-solution benchmark from 31.3% to 49.2%, and multi-teacher on-policy distillation (MOPD) then merges GiGPO specialists for macOS, Linux, Windows, and Web into a single cross-platform agent. A trace-based LLM-as-Judge evaluator agrees with human labels 94.3% of the time (83.2% on complex tasks) and drives a self-evolving benchmark.

  • GUI Agent
  • Qwen2.5
  • SFT
  • GRPO
  • GiGPO
  • DAPO
  • MOPD
  • LLM-as-Judge

Continually Learning Interactive Robot

An embodied agent that keeps expanding its behavior repertoire through ongoing human–robot interaction — new skills, new object concepts, and new language grounding are acquired online rather than baked in at training time.

  • HRI
  • Continual Learning
  • Multimodal
  • Agent
Thinking-with-Image: RL for Tool-Augmented Visual Reasoning

Thinking-with-Image: RL for Tool-Augmented Visual Reasoning

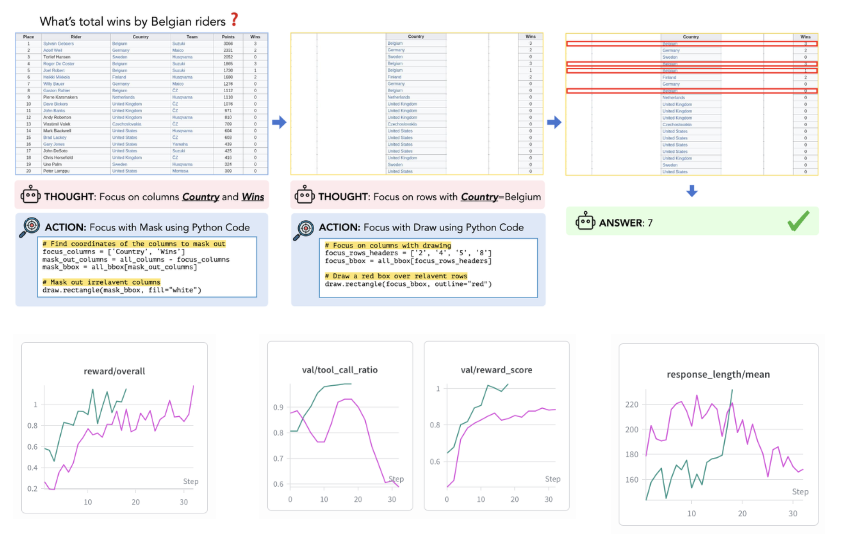
Reproduced and extended the VTool-R1 / ReFocus line of work so a VLM actively rewrites the chart it is reading — masking, boxing, and highlighting the relevant rows and columns mid-reasoning — turning thinking-in-text into thinking-in-image. The tool-using policy is trained end-to-end with RL (veRL + GRPO + DAPO). On ChartQA-style QA with Qwen2.5-VL-3B, answer accuracy rose from 62% to 96%.

  • RL
  • veRL
  • DAPO
  • GRPO
  • Qwen2.5-VL
  • vLLM

Real-time Packaging QA on a Hazardous-Explosive Production Line

Industrial vision QA system for a live hazardous-powder-explosive packaging line. ≥ 99% accuracy over a 30-day production run on the customer's RTX 4060; operator-level alarms via a fixed-protocol online-monitoring API.

  • Multi-scale Feat
  • Boundary Loss
  • Cython
  • TensorRT
  • Reparam

Legal-Domain LLM Assistant

A legal-service LLM built with Southwest University of Political Science and Law (SWUPL) and Beijing Chaoxing Tianxia: RoPE-extended long-context backbone, legal knowledge graph + vector DB, tool-calling and form-filling agent, and a small intent/NER model that rewrites user questions into formal logical symbols for reasoning.

  • LLM
  • RoPE
  • Knowledge Graph
  • RAG
  • Agent
  • NER

GNN-Accelerated MILP Scheduling for Industrial Electroplating

Formulated aerospace-part electroplating scheduling as a large-scale MILP and trained a GNN on historical schedules to provide warm-start solutions and variable priorities. FENNEL graph partitioning + high-confidence variable fixing reduced the effective search space by ≈ 10×; average solve time ≳ 10× faster.

  • MILP
  • GNN
  • FENNEL
  • Gurobi